Set the temperature, not the norm
A small study showing attention normalization mostly works by setting the starting scale.
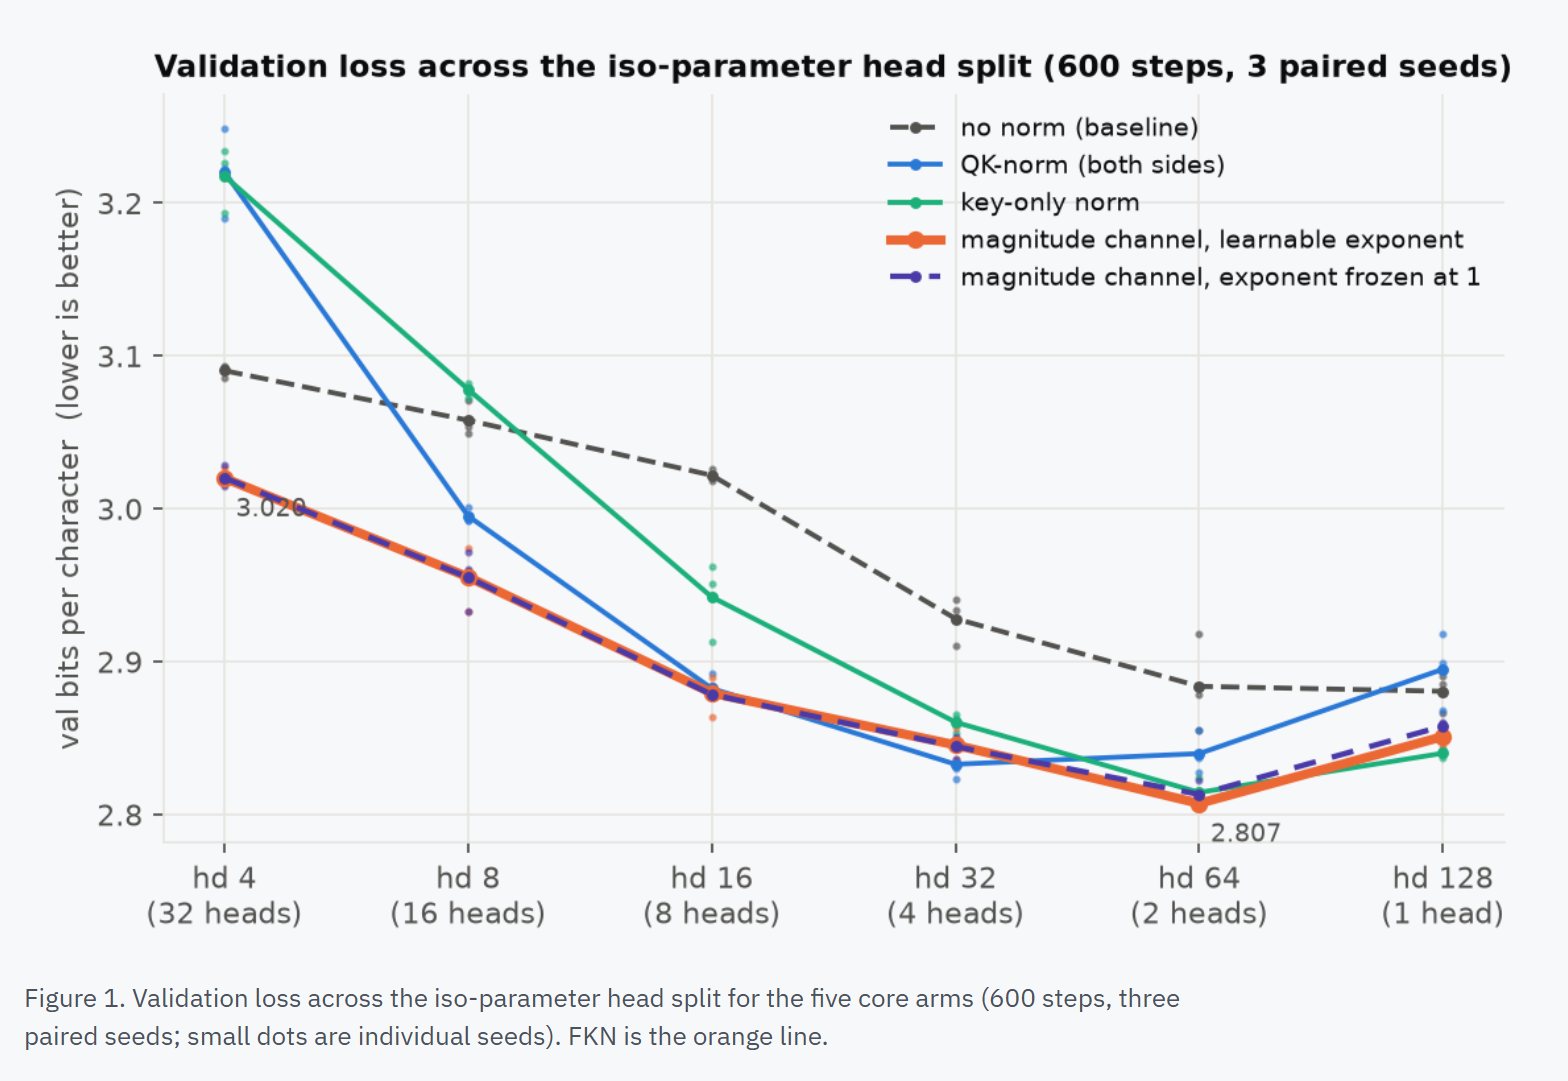
Many language models normalize parts of their attention. I wanted to know why it helps, so I swept head widths on a tiny character-level transformer, 0.42 million parameters, with parameters, compute and data matched.
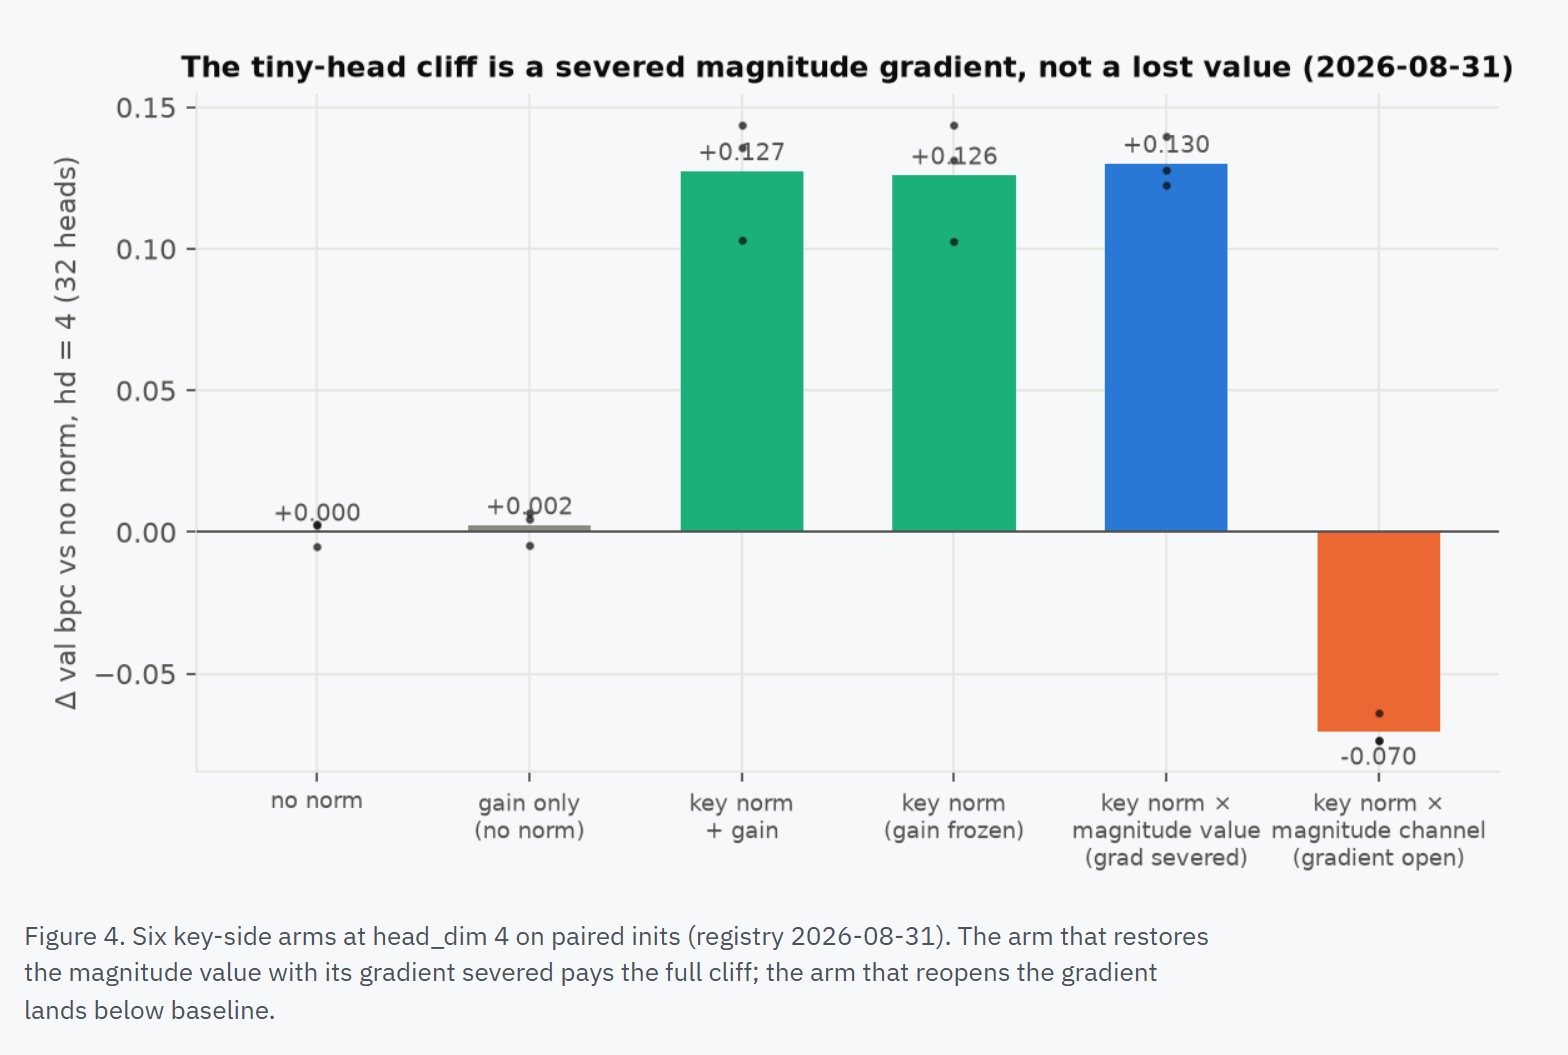
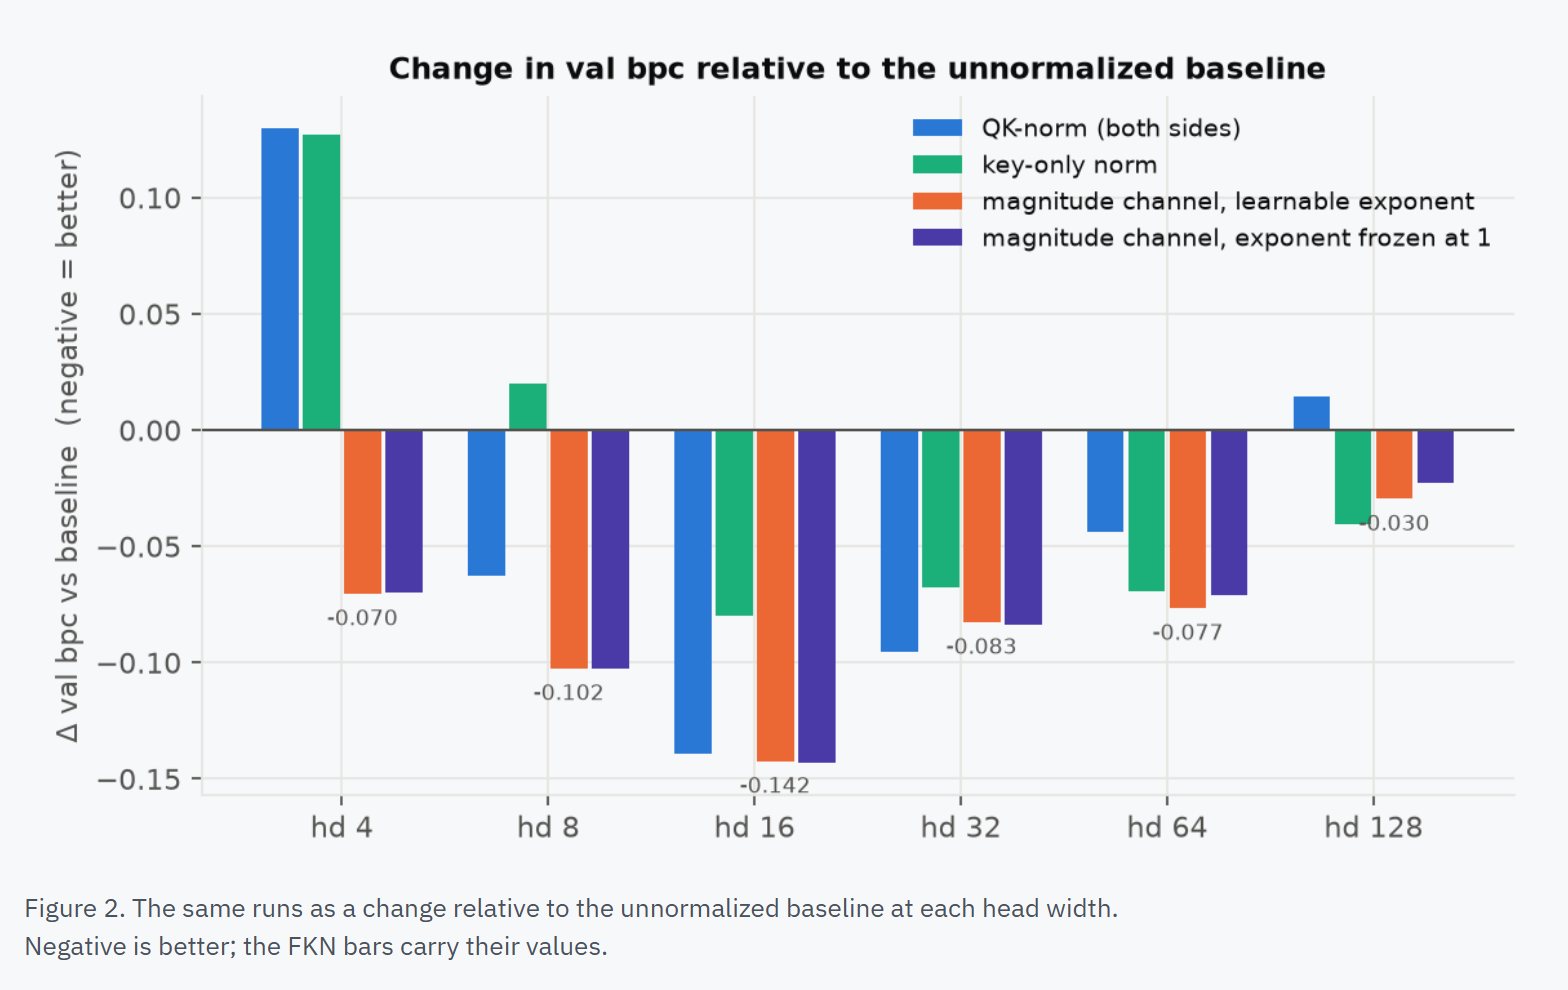
With 32 narrow heads, normalization made things worse by about 0.13 bits per character. With 8 wider heads, two-sided normalization helped by 0.14.
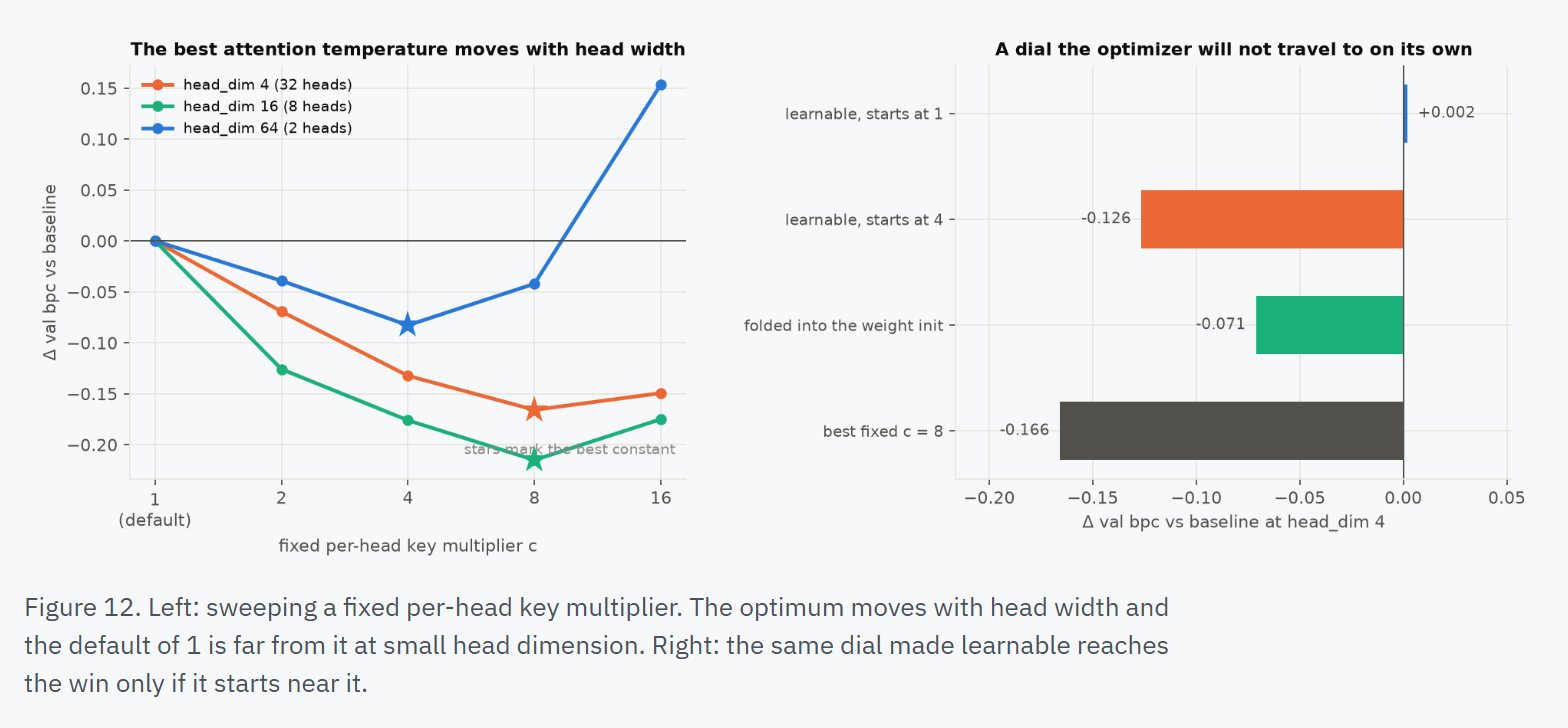
My own repair idea failed five kill tests. Then I found that one fixed multiplier on the keys beat every normalization variant, and the best value moves with head width.
All of it is small-scale, early in training, and CPU-only. The wide-head result did not hold when I trained three times longer.
- Model0.42 million parameter character-level transformer
- HardwareCPU only